What Is Strata? Why This Local LLM Engine Went Viral and How It Differs From Ollama
Updated 2026-11-04. This article is a reading of public sources. We have not installed Strata or run a benchmark ourselves.
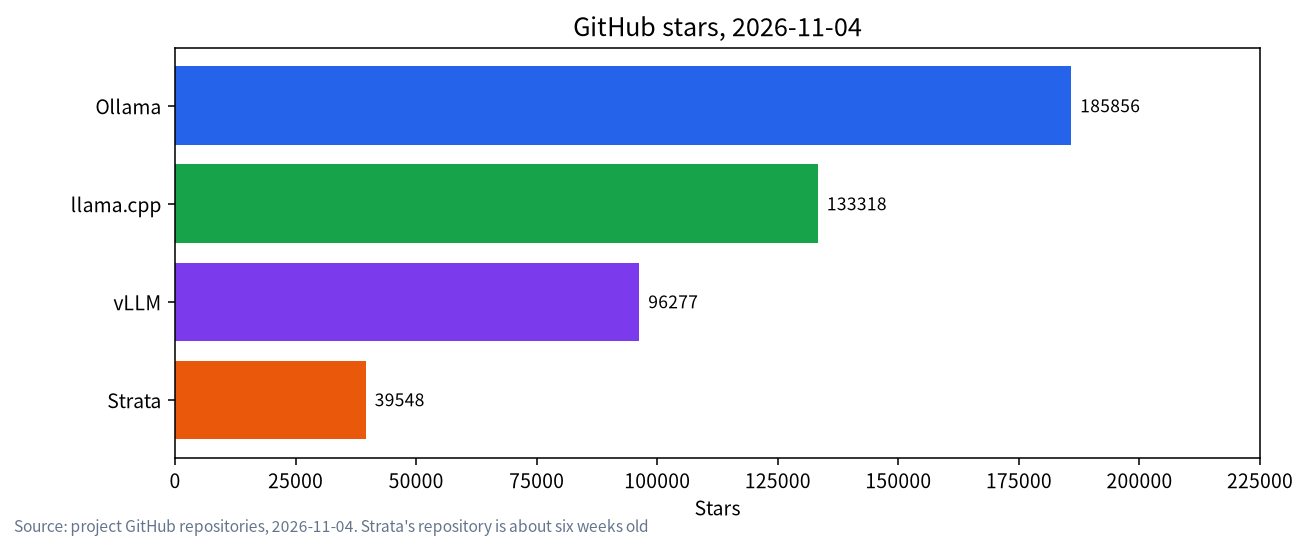
What is Strata? It is an open-source inference engine, shipped as a desktop app and a terminal tool, built around one idea: run a very large mixture-of-experts (MoE) model, such as the 125-billion-parameter Qwen3.8-Flash-Next, on an ordinary gaming PC by spreading the model across the graphics card, system RAM and the SSD. About six weeks after its repository was created it has roughly 39,500 GitHub stars, and almost every local-LLM forum has a thread about it. Below we explain what Strata is, why it spread so fast, what independent testers measured, and where the caveats are. It sits next to Ollama rather than replacing it, and the comparison is in our Strata vs Ollama article.
What is Strata, in one paragraph
Strata is published on GitHub under the MIT license, and the repository is written mostly in C++. It installs as a desktop app (Windows, Linux AppImage, macOS) or as a terminal tool you start with strata launch. Once a model is running it serves an OpenAI Chat Completions API, an Anthropic Messages API and a Responses API on your own machine, so coding tools can connect to it. The documentation lists ggml, the tensor library behind llama.cpp, as a third-party component, but the scheduling that makes Strata different is its own.
| Item | Value on 2026-11-04 | Where it comes from |
|---|---|---|
| Repository created | 2026-09-24 | GitHub |
| Stars / forks | 39,548 / 4,298 | GitHub |
| Latest release | v0.2.10 (2 Nov 2026, UTC) | GitHub releases |
| Engine license | MIT | Repository |
| Model license | Qwen3.8-Flash-Next weights use the Qwen Community License 1.0, not MIT | Project docs |
| Default local address | http://127.0.0.1:8080 |
Install guide |
| Telemetry | None and no account, according to the project | Safety document |
| Outside security audit | Not yet, according to the same document | Safety document |
The models Strata runs
A mixture-of-experts model has many specialist sub-networks (“experts”) and uses only a few per token. Qwen3.8-Flash-Next has about 125 billion parameters in total but roughly 6 billion active per token (512 experts per layer, 24,576 in all, and a native context of 262,144 tokens). That ratio, about 5% of the weights per token, is what Strata exploits.
| Model | Size | What the docs say |
|---|---|---|
| Qwen3.8-Flash-Next | 125B total, ~6B active | Four quantizations needing 37.6 GB (Q2_0), 39.2 GB (IQ2_XS), 47.0 GB (IQ3_XXS) or 54.8 GB (IQ3_S) of RAM plus VRAM |
| Qwen3.6-35B-A3B | 35B total, ~3B active | Unsloth packs, 32 to 52 GB of RAM |
| DeepSeek V4.1-Flash | Very large | 239 to 274 GB download, 12 GB GPU, 46 to 64 GB of RAM; see our DeepSeek V4.1 Flash on 12GB article |
For background on why MoE models behave this way, see our MoE models guide.
How Strata works: three tiers
Strata’s own HOW_IT_WORKS document describes three tiers.
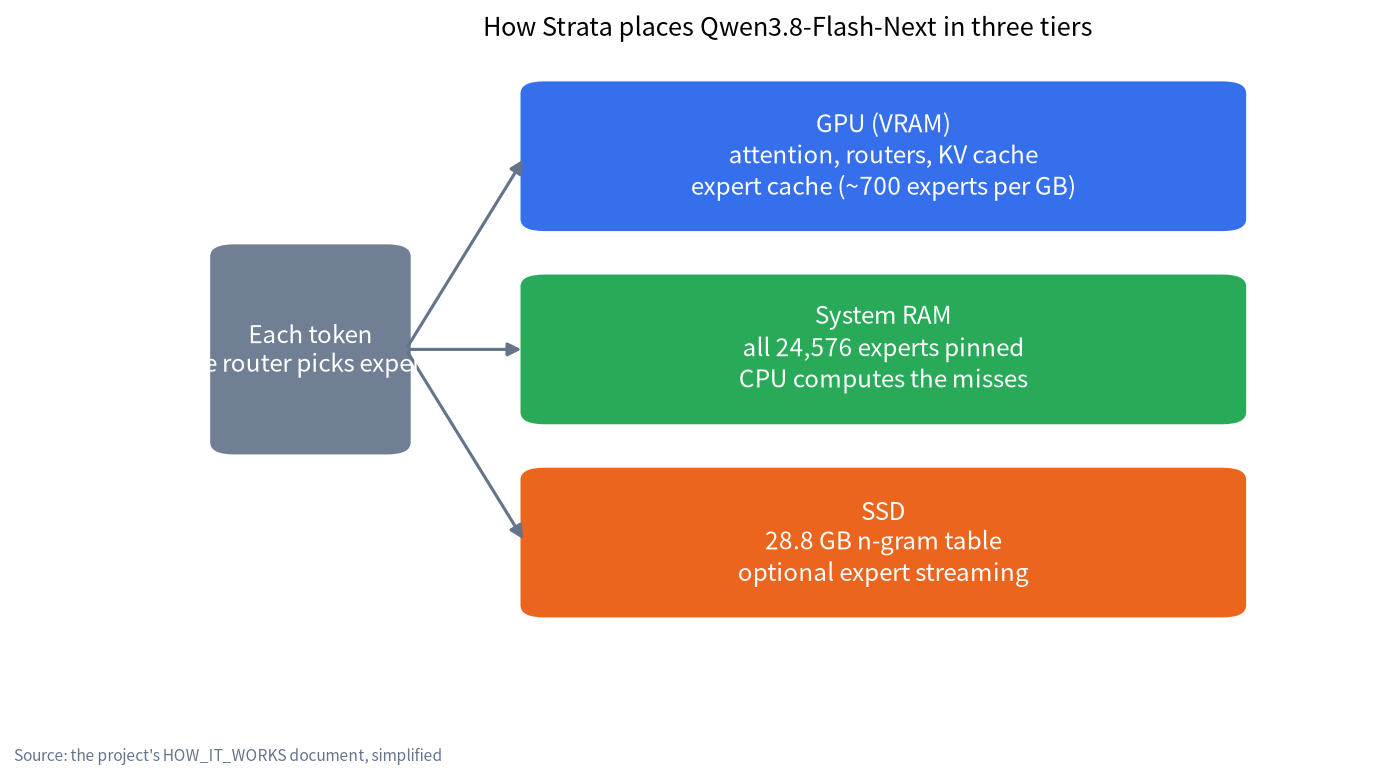
- GPU. Attention layers, routers, shared experts, the output head, the multi-token-prediction (MTP) draft layer, the KV cache and an expert cache that fills whatever VRAM is left. The docs say each extra gigabyte of VRAM holds roughly 700 more experts.
- RAM. All 24,576 experts, pinned in memory. When the router picks an expert that is not in VRAM, the CPU computes it in place instead of copying it to the card.
- SSD. A 28.8 GB n-gram embedding table, of which only a few rows are read per token. An optional
--mmap-expertsmode can also stream experts from disk when RAM is short, which works but is much slower.
Speed then depends on how often the experts a token needs are already on the GPU. PC Watch’s test on an RTX 3060 reported about 3,031 experts on the card and a cache hit rate near 72% with the IQ2_XS file, and about 1,104 experts and 56% with IQ3_S. The project’s paper credits MTP speculative decoding with a 1.6 to 1.8 times speed-up; that figure is the authors’ own.
Why Strata went viral
Based on the sources we read, several things came together:
- A one-click install. A Windows installer, a Linux AppImage and a macOS disk image, plus a one-line terminal installer. The engine for your GPU downloads on first start.
- A headline people could repeat. “A 125B model on a 12 GB graphics card” is easy to share, even though the full picture needs 64 GB of RAM for the larger quantizations.
- Timing. Qwen3.8-Flash-Next was the model people were already talking about in October.
- Coding-agent support.
strata connectwrites configuration for Claude Code, Codex CLI, OpenCode, Hermes Agent, OpenClaw and others. - A fast release pace. Six releases between 25 October and 2 November.
- Attention on Hacker News. One thread reached 940 points and 420 comments when we read it, and a second thread complained that local-LLM discussions were being flooded with Strata links. Read the main thread.
What independent testers reported
None of the numbers below are ours. They come from different hardware, Strata versions and quantizations, so treat them as a range, not a leaderboard.
| Source | Hardware | Model and quant | Reported result |
|---|---|---|---|
| Strata community benchmark (v0.1.41) | RTX 3060 12 GB, DDR4-3200 | Q2_0 / IQ2_XS / IQ3_XXS | 42.9 / 45.5 / 26.2 tok/s decode at a 4,096-token prompt |
| PC Watch (v0.1.38) | RTX 3060 12 GB, Core i9-12900, 64 GB DDR4 | IQ2_XS; IQ3_S | 34 to 44; 25 to 32 tok/s. About 7 s to first token for a 5.9k-token prompt, about 25 s for 23k |
| note.com, usshi_it | RTX 3060 12 GB, Ryzen 5 3600, 48 GB | Q2_0 | 44.49 tok/s decode, 326.68 tok/s prefill, 1.60 s to first token |
| Siddhant Dembi | RTX 3060 in a Proxmox VM, about 50 GiB RAM | IQ3_S | About 36 to 38 tok/s; needed a reasoning budget to avoid endless thinking |
| AkitaOnRails | RTX 5090 | IQ3_S | About 159 tok/s, and a score of 91 on the author’s own coding benchmark |
| arm1.ru | RTX 5080 Laptop, 30 GB RAM | Flash-Next vs Qwen3.8-27B in llama.cpp | Similar coding quality; Strata used about 21 GB of RAM, pushed 4 to 5 GB into swap and read about 6.9 TB from the SSD in a 1.3-hour run |
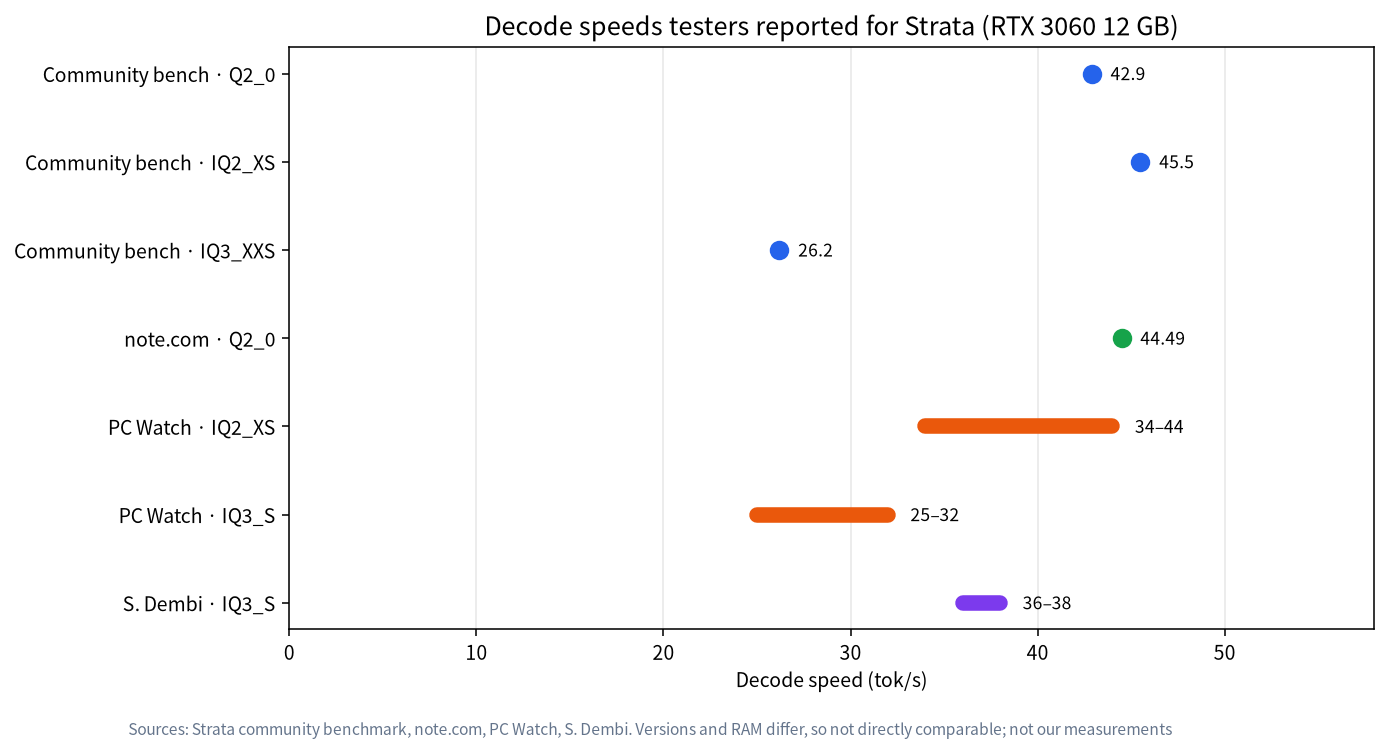
One card, the RTX 3060, produces everything from about 20 to 45 tokens per second depending on quantization, version and memory, which is why “how fast is Strata” has no single answer.
Caveats and criticism
- Quality at 2 to 3 bits. The project says IQ3_S matches the full model on its published tests. That is the authors’ claim. PC Watch found code generation at IQ2_XS a step below IQ3_S, and Hacker News contains skeptical comments, including one user who reported a vision test where Strata’s error was larger than llama.cpp’s with the same weights. We could not verify that.
- Long prompts are slow on a 12 GB card. PC Watch measured about 25 seconds to first token for a 23k-token prompt, which hurts coding agents that send whole files.
- Memory pressure. The arm1.ru test shows a laptop with 30 GB of RAM swapping and the SSD busy for the whole run.
- A young project. The repository is six weeks old, and releases arrive every two days. Settings and speeds change between versions, and the Strata docs themselves state it has had no outside security audit.
- Piped installer. The one-line installer is convenient but is a script you run with your user rights. Read it, or use the signed app installer.
- Model license. The engine is MIT, but the Qwen weights are under the Qwen Community License; read it before commercial use.
- Numbers do not agree everywhere. Some posts say 176B parameters; the repository says 125B, which is what we use.
Strata vs Ollama at a glance
| Strata | Ollama | |
|---|---|---|
| Main goal | Run specific very large MoE models on small VRAM by tiering GPU, RAM and SSD | General model manager: pull, run and serve many small and mid-size models |
| Stars (2026-11-04) | 39,548 | 185,856 |
| Models | Qwen3.8-Flash-Next, Qwen3.6-35B-A3B, DeepSeek V4.1-Flash | A large library; see ollama.com/library |
| Latest release we saw | v0.2.10 (2 Nov) | v0.40.14 (3 Nov) |
| Qwen3.8-Flash-Next | Runs on Windows, Linux and macOS | The library page showed one tag, 125b-mlx (105 GB, for Apple Silicon); we found no tag for NVIDIA GPUs and did not test |
They overlap less than the headlines suggest. If you want one tool for many models, Ollama is still the easier choice; if you want this particular model class on a 12 to 24 GB card, Strata is the one built for it. The full comparison with llama.cpp and LM Studio is in our comparison article, installation is in the install guide, and the hardware side is in our hardware requirements article. If you are new to Ollama itself, start with our Ollama install guide.
What we did and did not do
We read the Strata repository documents, its release notes, Ollama’s release notes and library page, and the third-party reports linked above on 2026-11-04. We did not install Strata, download any weights or measure any speed. Every number is attributed to its source.
FAQ
What is Strata in simple terms?
Strata is a free program that lets a normal PC run a very large AI model by keeping the busiest parts on the graphics card, the rest in RAM and a lookup table on the SSD. It is an engine plus a chat app, not a model.
Is Strata free and open source?
The engine is MIT-licensed. The models it downloads have their own licenses; Qwen3.8-Flash-Next uses the Qwen Community License 1.0.
Is it really a 125B model on a 12 GB GPU?
The model has 125 billion parameters in total but about 6 billion are active per token. Strata still wants roughly 38 to 55 GB of combined RAM and VRAM for the model plus about 80 GB of disk, so the 12 GB card is only the minimum for the GPU part.
Can I run Strata and Ollama on the same PC?
Yes. Strata listens on port 8080 by default and Ollama on 11434, but both want the same VRAM and RAM, so run one large model at a time. The install guide covers this.
Is Strata safe to install?
The project says it has no telemetry and no accounts, and its server listens on localhost, but it also says there has been no outside security audit. Install it on a machine without sensitive data first, and download only from the official repository.
Does Strata replace Ollama?
No. They solve different problems. Many people will keep Ollama for everyday models and add Strata for one large MoE model.
Talk with us
Have a GPU, RAM and budget question? Join the community or email admin@microaione.com and we will work through it with you. If you would rather have a machine built and tested for you, see our machines and solutions guide.