LLM Leaderboard Top 10: Which Open Models Can You Actually Run Locally? (Nov 2026)
Every time a new model ships, a screenshot appears showing it “topping the leaderboard.” But if you want to run a model on your own computer, the LLM leaderboard top 10 is a list you can look at and not touch: almost every name near the top is a mixture-of-experts model with hundreds of billions of parameters, far beyond a single consumer card. This article gives a November 2026 snapshot of the LMArena open-license top 10, adds the Artificial Analysis index, estimates how large each model is at Q4 quantization, and tells you which names are realistic locally, plus the mid-sized models that actually suit personal hardware.
How we checked this: The LMArena figures are a snapshot of the open-license board dated 2026-10-27; the Artificial Analysis figures were read on 2026-11-04. Boards change constantly, so treat these as a snapshot, not a verdict. Q4 sizes are estimates at about 0.61 GB per billion parameters. We did not download or run any of these models. The two boards measure different things, so we do not average or merge their scores.
Key points (updated 2026-11-04)
- LMArena open-license top 10 (snapshot 2026-10-27): Kimi K3 (Max) 1488, GLM-5.3 (Max) 1481, MiMo-V2.6-Pro 1480, GLM-5.3-Flash 1477, DeepSeek-V4.1-Flash-20260910 (Max) 1476, followed by GLM-5.2, MiMo-V2.5-Pro, GLM-5.1, DeepSeek-V4-Pro and Kimi K2.6.
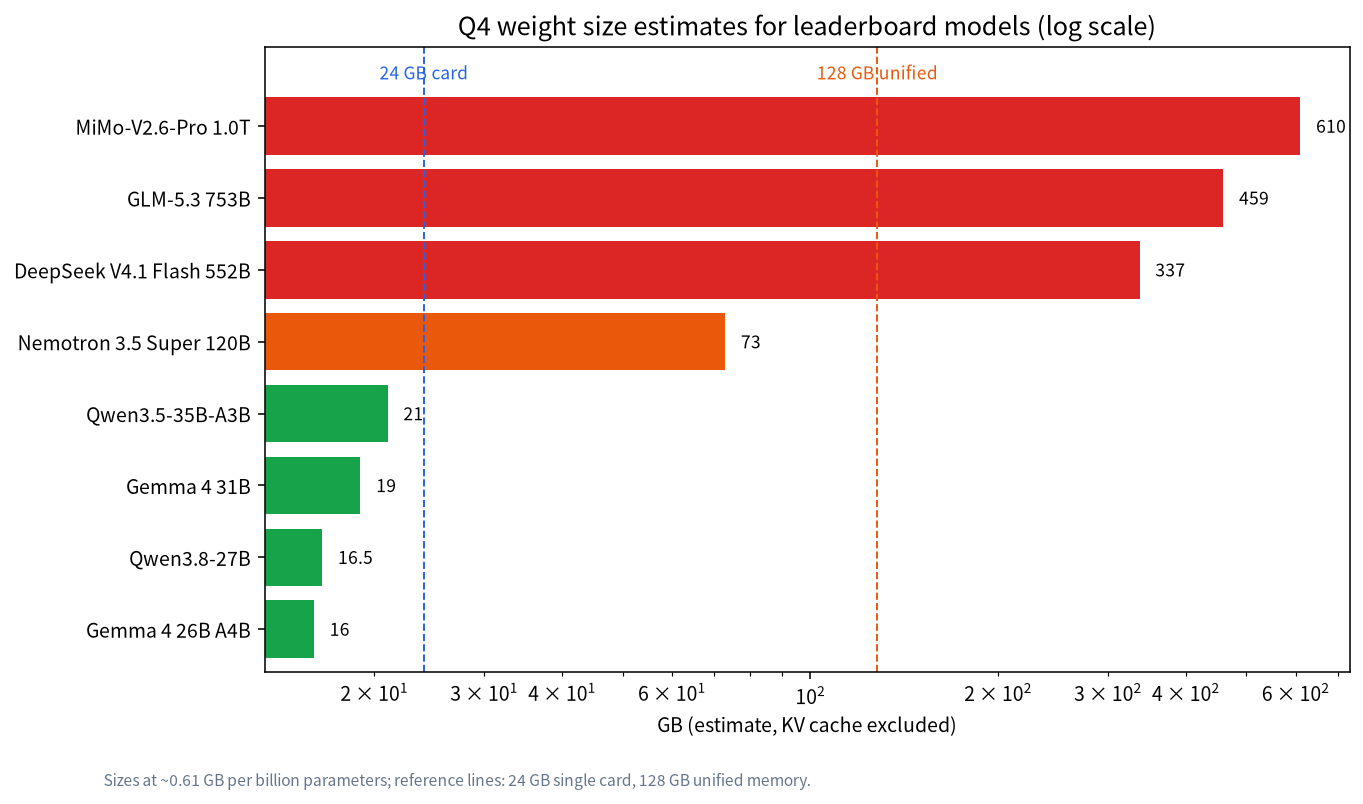
Where total parameters are published, top-10 models are huge: DeepSeek V4.1 Flash is 552B (16B active), GLM-5.3 is 753B, MiMo-V2.6-Pro about 1.0T. Our Q4 estimates are roughly 337 GB, 459 GB and 610 GB, beyond a single card or a 128 GB desktop.
Realistic local picks sit lower on the board: Gemma 4 31B (Arena score 1452, Apache 2.0), Gemma 4 26B A4B (1438) and Qwen3.8-27B (1436, Apache 2.0). Their Q4 estimates are about 16 to 19 GB, which a 24 GB card can hold, with context headroom to watch.
- The two boards cannot be averaged: LMArena is human preference voting, while the Artificial Analysis index leans toward agentic and professional tasks.
LLM leaderboard top 10: the LMArena open-license snapshot
LMArena (now at arena.ai) lets you filter its text board by licence. Below is the top 10 under the “open license” filter. The scores are Elo-style preference scores, and the gaps are small, so there is no safe conclusion from differences between the first few places.
| Rank | Model | Arena score | Note |
|---|---|---|---|
| 1 | Kimi K3 (Max) | 1488 | Listed with a custom licence; read the terms before use |
| 2 | GLM-5.3 (Max) | 1481 | AA page shows 753B total, 40B active |
| 3 | MiMo-V2.6-Pro | 1480 | AA page shows about 1.0T total, 42B active |
| 4 | GLM-5.3-Flash | 1477 | — |
| 5 | DeepSeek-V4.1-Flash-20260910 (Max) | 1476 | AA page shows 552B total, 16B active |
| 6 | GLM-5.2 (Max) | 1475 | — |
| 7 | MiMo-V2.5-Pro | 1467 | — |
| 8 | GLM-5.1 | 1465 | — |
| 9 | DeepSeek-V4-Pro (High, 20260813) | 1465 | — |
| 10 | Kimi K2.6 | 1461 | — |
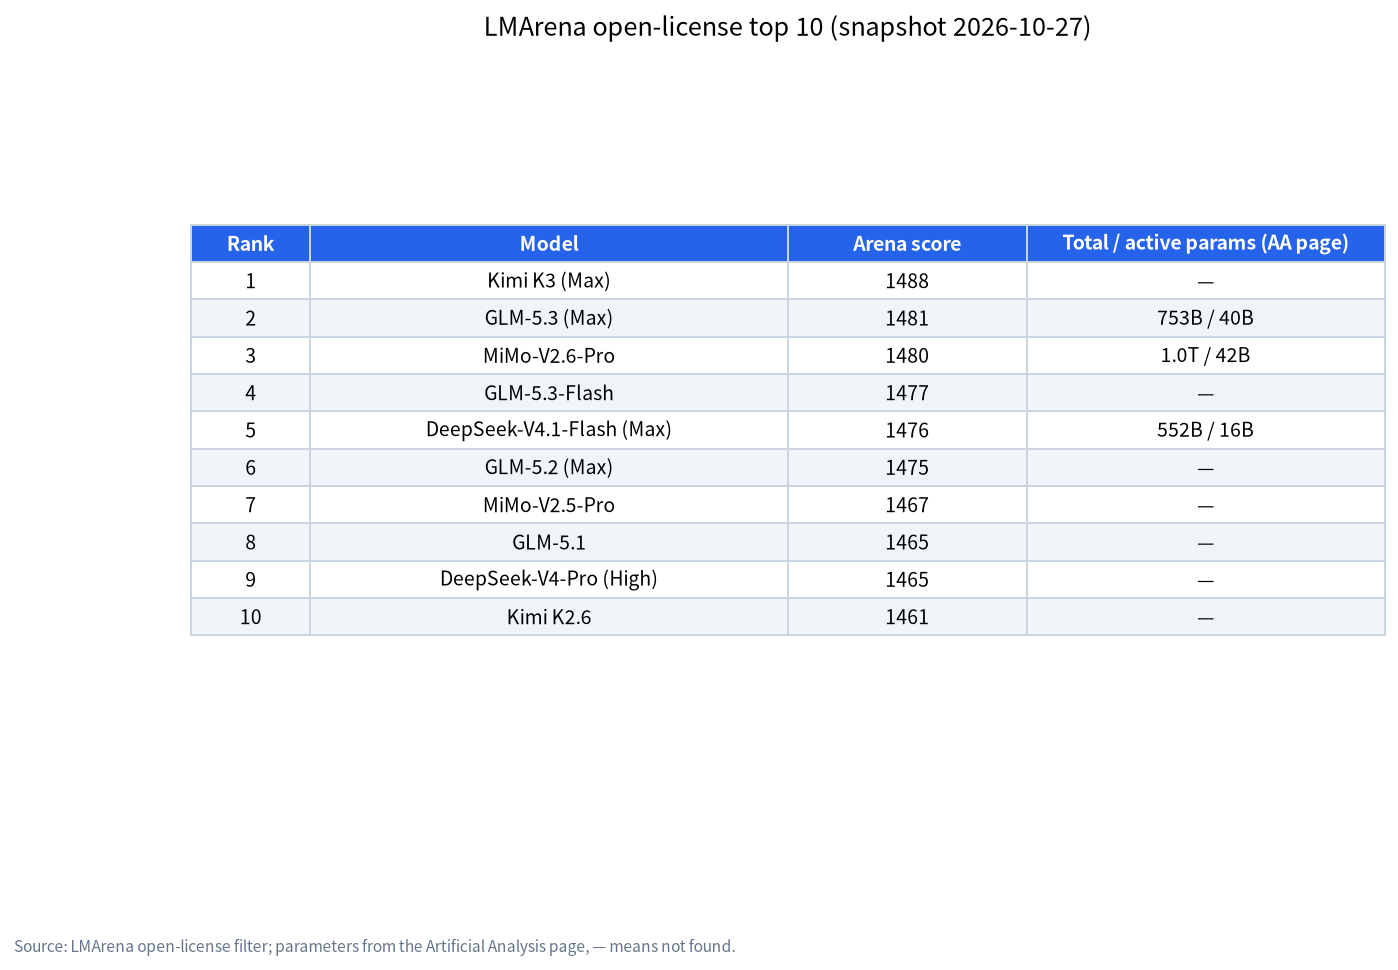
Two things stand out. Only four families (Kimi, GLM, MiMo, DeepSeek) fill the top 10; all four come from Chinese teams, which is what most searches for a “domestic Chinese LLM top 10” are after, though there is no single agreed definition of such a list. And the gap between first and tenth is just 27 points, on a board that moves with every new vote. It is more honest to read this as a “first-tier list” than as a precise ranking.
The second board: the Artificial Analysis index
The Artificial Analysis (AA) open-weights page publishes its own Intelligence Index (v5.0.1), built from several evaluations that lean toward agentic and professional tasks. These are the values we read:
| Model | AA index | Note |
|---|---|---|
| DeepSeek V4.1 Flash 1017 (Max) | 33 | 552B, 16B active; page lists about 169 tokens/s (hosted) |
| GLM-5.3 | 32 | 753B, 40B active |
| MiMo-V2.6-Pro | 30 | about 1.0T, 42B active |
| Ling 3.1 Flash 1019 | 30 | — |
| MiniMax-M3.1-Flash | 29 | — |
| Step 5 Preview | 29 | — |
| Mistral Large 4 | 26 | about 1.1T |
| Qwen3.8 27B (Xhigh) | 20 | 27B dense, 256k context |
| Nemotron 3.5 Super VL | 14 | — |
Comparing the boards shows that the same model can sit in a different relative place on each. Qwen3.8 27B scores only 20 on the AA index but ranks within the top 30 of LMArena’s open board. Neither board is wrong; they measure different things. One more note: Hugging Face’s Open LLM Leaderboard was retired in March 2025, so any article still quoting it is out of date.
Which of the top 10 can run locally?
What decides whether a model runs is weight size, not rank. A rough Q4 size estimate is about 0.61 GB per billion parameters (an estimate; real files depend on the quantization recipe). Compare that to common device capacities:
| Model | Total params | Q4 size estimate | Where it can run |
|---|---|---|---|
| DeepSeek V4.1 Flash | 552B | about 337 GB | Multi-GPU servers or very large memory; not one card, not a 128 GB desktop |
| GLM-5.3 | 753B | about 459 GB | Same |
| MiMo-V2.6-Pro | about 1.0T | about 610 GB | Same |
| Nemotron 3.5 Super VL 120B (preliminary) | 120B | about 73 GB | 128 GB unified-memory class |
| gpt-oss-120b | about 120B | llama.cpp guide quotes about 68.5 GB at 128K context | 128 GB unified memory or large-VRAM machines |
| Gemma 4 31B | 31B | about 19 GB | 24 GB card, watch context |
| Qwen3.8-27B | 27B | about 16.5 GB | 24 GB card |
| Gemma 4 26B A4B | 26B (about 4B active) | about 16 GB | 24 GB card; MoE is friendlier on speed |
| Qwen3.5-35B-A3B | 35B (about 3B active) | about 21 GB | Tight on 24 GB; keep context short |
The local-friendly models above come from lower on LMArena’s open board: Gemma 4 31B (1452), Gemma 4 26B A4B (1438), Qwen3.8-27B (1436), Qwen3.5-27B (1409), Qwen3.5-35B-A3B (1394), gpt-oss-120b (1352) and gpt-oss-20b (1317; the llama.cpp guide quotes about 17.9 GB at 128K context). Before downloading, check fit with the VRAM calculator guide and the model size chooser; the behaviour of mixture-of-experts models is covered in MoE models locally.
How to read a leaderboard: four steps
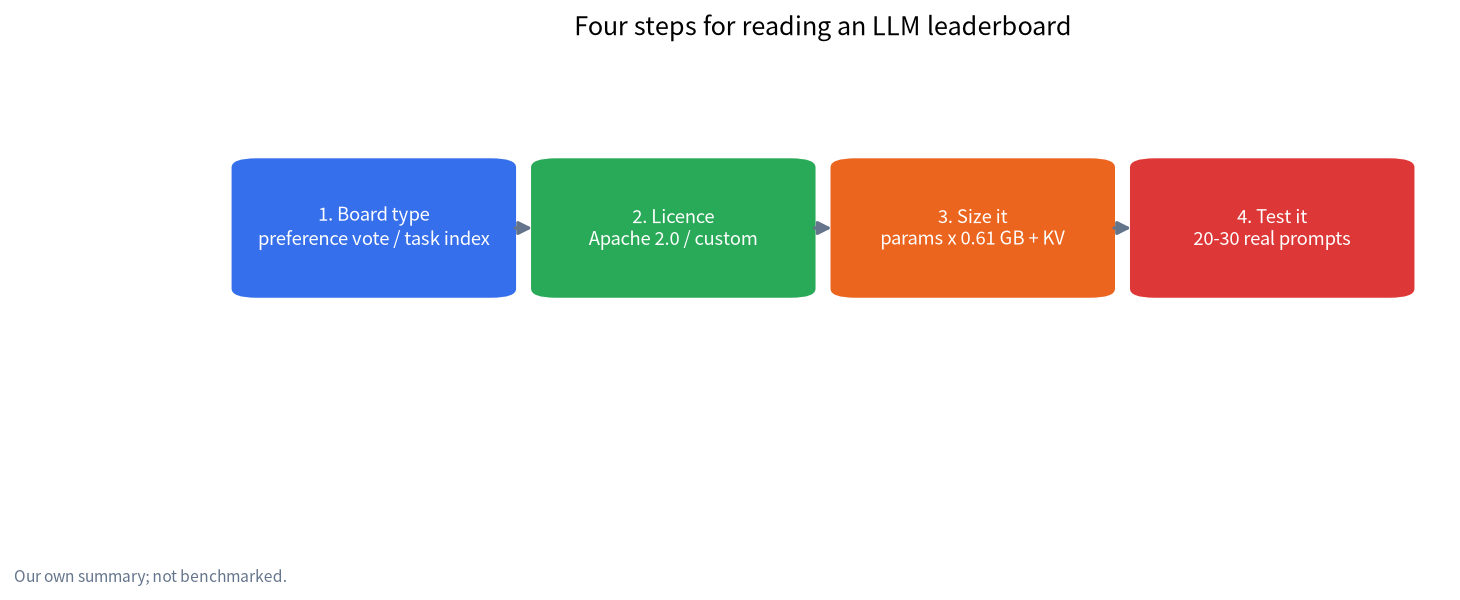
- Know what the board measures. LMArena is blind user preference; the AA index leans toward tasks and agents; other boards may be single benchmarks. See how to read LLM benchmarks for the details.
- Check the licence. Open weights does not mean “do anything.” Kimi K3 is shown with a custom licence on the board and its terms need reading; Gemma 4 31B and Qwen3.8-27B are shown as Apache 2.0. Leave legal judgement to your counsel.
- Size it. Estimate Q4 size as parameters times 0.61 GB per billion, add KV cache and 1 to 2 GB of overhead, and compare with your device.
- Test on your own tasks. A gap of a few dozen points may be invisible on your real problems.
Worked example: a single 24 GB card
Suppose you have one 24 GB card and want to know whether Gemma 4 31B from the board fits.
- Usable VRAM is roughly 0.92 to 0.95 of nominal, so about 22.1 to 22.8 GB for a 24 GB card (a rule-of-thumb range that varies by system).
- Gemma 4 31B at Q4 is estimated at 31 x 0.61, or about 18.9 GB.
- Runtime overhead of 1 to 2 GB leaves about 22.1 – 18.9 – 2 = 1.2 GB up to 22.8 – 18.9 – 1 = 2.9 GB for the KV cache.
- How much context that buys depends on the model’s layers, KV heads and cache precision, so plug the real architecture into the VRAM calculator. The conclusion is “it fits, but context headroom is tight.”
Run the same arithmetic on Qwen3.8-27B: 27 x 0.61 is about 16.5 GB, leaving roughly 3.6 to 5.3 GB, which is more comfortable. Gemma 4 26B A4B at about 15.9 GB leaves even more. A few dozen leaderboard points can cost you a very visible amount of memory headroom, which is why we put “fits with room to spare” ahead of “rank” when choosing.
The speed column is not your local speed
The tokens-per-second figure on the AA page (for example about 169 for DeepSeek V4.1 Flash 1017) is a hosted API output speed. It reflects the provider’s deployment and hardware, not your GPU. A rough local ceiling is still “memory bandwidth divided by model size”; see why LLMs need a GPU. Mixture-of-experts models read only their active parameters per token, so they are often faster at the same file size, but all the weights still have to sit in memory or VRAM.
Three kinds of reader, three ways to use the board
A hobbyist with a 12 GB to 24 GB card. Do not chase the top 10. Look in the range up to 27B to 35B for models that rank well and fit. If you only have 12 GB, 8B to 14B models will feel smoother on your hardware, and “fits entirely in VRAM” matters far more than a rank difference.
A small team building a shared internal service. You care about concurrency and stability more than single-chat preference scores. Start with a shared local LLM for small teams, pick two or three candidates from the board, and blind-test them on your own questions.
A company that wants the full top-10 models. That means multi-GPU servers with high hardware cost, plus licence, operations and security work; see enterprise private deployment. If usage is occasional, renting compute or calling an API is often cheaper; the comparison is in local vs cloud API.
How to track a board without relying on screenshots
- Write the date. Every time you quote a score, note the snapshot date, as we did with 2026-10-27 and 2026-11-04.
- Note the filters. LMArena lets you filter by licence, style control and more; ranks differ under each filter.
- Look at the uncertainty. Arena pages show a confidence range, and neighbouring ranks are often indistinguishable.
- Cross-check. A model that is high on both boards is more worth the download.
- Keep a tiny test set. Prepare 20 to 30 questions you really ask and rerun them when you switch models; that tells you more than any board.
Common mistakes
- Treating “first on the board” as “right for me.” The leader is usually hundreds of billions of parameters and will not fit locally.
- Adding or averaging scores from two boards. The scales differ; the result means nothing.
- Reading tiny Arena gaps as real. A difference of a few dozen points may be irrelevant statistically and practically.
- Ignoring the licence. “Open” comes in many kinds; read the terms before commercial use.
- Treating a snapshot as permanent. Ranks change with new models; ours are dated 2026-10-27 (LMArena) and 2026-11-04 (AA).
- Forgetting quantization loss. Q4 costs some quality, and board scores usually reflect the original or higher-precision release.
What we checked and what we did not
The LMArena and AA values come from what the two public pages display, and we do not vouch for their methods. Parameter counts come from the AA page. Q4 sizes use 0.61 GB per billion parameters, and the gpt-oss sizes come from the llama.cpp guide. We did not download or run any of these models and did not read every licence in full; we only repeat the licence category the board page shows.
FAQ
How should I read top-10 domestic / China AI LLM rankings for local use?
Current AI LLM top-10 leaderboards and latest China AI model top-10 rankings mostly reflect online evals—not what fits your GPU. For local use, pair leaderboard rank with VRAM and quantization fit; see the local-fit table above.
What are the LLM leaderboard top 10 models right now?
On the LMArena open-license board snapshot of 2026-10-27: Kimi K3 (Max), GLM-5.3 (Max), MiMo-V2.6-Pro, GLM-5.3-Flash, DeepSeek-V4.1-Flash (Max), GLM-5.2, MiMo-V2.5-Pro, GLM-5.1, DeepSeek-V4-Pro and Kimi K2.6. The board changes over time.
Can the top 10 models run on a local machine?
Mostly no. Where parameters are published, the top-10 models are hundreds of billions to trillions of parameters, and Q4 estimates run to hundreds of GB, which needs a multi-GPU server. Personal machines suit the 27B to 35B models on the same board.
Which board is more trustworthy, LMArena or Artificial Analysis?
They measure different things: human preference voting versus a task-oriented index. Read both, then test on your own tasks, and do not average the scores.
Which models from the board fit a 24 GB card?
At our Q4 estimates, Gemma 4 31B, Qwen3.8-27B and Gemma 4 26B A4B (about 16 to 19 GB) fit; Qwen3.5-35B-A3B at about 21 GB is tight.
Can I use any open board model commercially?
Not necessarily. The board shows a licence category, some Apache 2.0 and some custom. Read the terms and consult counsel before commercial use.
Will the ranking change?
Yes. Boards move with votes and new releases; this article is a snapshot.
Want help choosing a model for your hardware?
Come to the community or email admin@microaione.com with your VRAM, RAM and use case. Our Shenzhen team can help you pick a configuration, and we will be clear about which conclusions are only estimates.
References: LMArena text board (open-license filter), Artificial Analysis: open-source models, llama.cpp gpt-oss guide, Hugging Face Open LLM Leaderboard (retired).