Voyage 4 Large Review: The Best Embedding Model? Versus Qwen3-Embedding, Gemini and Local voyage-4-nano
Voyage 4 Large is the flagship text embedding model Voyage AI released with the voyage-4 family in January 2026, which the company calls the first production mixture-of-experts (MoE) embedding model. The case for it being the best embedding model rests mainly on Voyage’s own published RTEB comparison: averaged over 29 datasets, NDCG@10 beats Gemini Embedding 001, Cohere Embed v4 and OpenAI v3 Large. But on the public MTEB English retrieval board we could not find it in the top ten, where open-weights models such as Qwen3-Embedding-8B sit. This article puts vendor measurements, public boards, prices and storage costs side by side to answer the local reader’s question: for RAG, should you pay for Voyage 4 Large, or use voyage-4-nano or Qwen3-Embedding, which you can download and run?
Verification note: Voyage 4 Large’s performance figures come from Voyage’s official blog (2026-01-15) and are all vendor-measured; prices were read from Voyage’s official pricing page; the MTEB English retrieval board was read from modelmenu.dev (updated 2026-10-27); Qwen3-Embedding figures come from its Hugging Face model card, where the MTEB scores are dated June 2025 and are no longer current; voyage-4-nano details come from its Hugging Face model card. We have not evaluated any embedding model ourselves; storage and cost figures are our arithmetic.
Key takeaways (Updated 2026-11-01)
- Vendor measurement: averaged over 29 RTEB datasets, voyage-4-large beats voyage-4 by 1.87% NDCG@10, Gemini Embedding 001 by 3.87%, Cohere Embed v4 by 8.20% and OpenAI v3 Large by 14.05%.
Price: voyage-4-large is $0.12 per million tokens, voyage-4 is $0.06 and voyage-4-lite $0.02; the first 200 million tokens per account are free.
Local: voyage-4-nano (Apache-2.0, about 340 million parameters) shares the flagship’s embedding space; Qwen3-Embedding comes in 0.6B, 4B and 8B.
The Short Answer: The Lead Comes From Vendor Measurement
| Source | Where Voyage 4 Large stands | Caveat |
|---|---|---|
| Voyage official blog (RTEB, 29 datasets) | Ahead of the Gemini Embedding 001, Cohere Embed v4 and OpenAI v3 Large it compares against, and of its own voyage-4 and voyage-4-lite | Vendor-measured; the comparison set is chosen by the vendor; the blog compares mean NDCG@10 on RTEB |
| MTEB English retrieval (modelmenu.dev) | Not seen in the top ten | We did not see an MTEB submission; the leader is Yuan Embedding 2.0 En (70.7) |
| Price | $0.12 per million tokens | Cheaper than Gemini Embedding 001 (about $0.15) |
The point is that “absent from a board” does not mean “bad”; it means the model has not been measured with the same ruler as the models on that board. RTEB is a retrieval benchmark Voyage itself launched and uses in its evaluations, and we cannot independently verify its dataset composition in this article, so we only relay the vendor’s conclusion.
The MTEB English Retrieval Board
The modelmenu.dev MTEB English retrieval board (updated 2026-10-27; figures are mean nDCG@10 times 100):
| Rank | Model | Mean nDCG@10 | Note |
|---|---|---|---|
| 1 | Yuan Embedding 2.0 En | 70.7 | — |
| 2 | Ingot 8B R3 | 70.0 | — |
| 3 | Qwen3-Embedding-8B | 69.4 | 4096 dimensions, about 33K context, open weights |
| 4 | Geevec | 68.8 | — |
| 5 | Qwen3-Embedding-4B | 68.5 | 2560 dimensions, open weights |
| 6 | Seed1.5 | 67.5 | — |
| — | Gemini Embedding 001 | 64.4 | 3072 dimensions, 2K context, about $0.15 per million tokens |
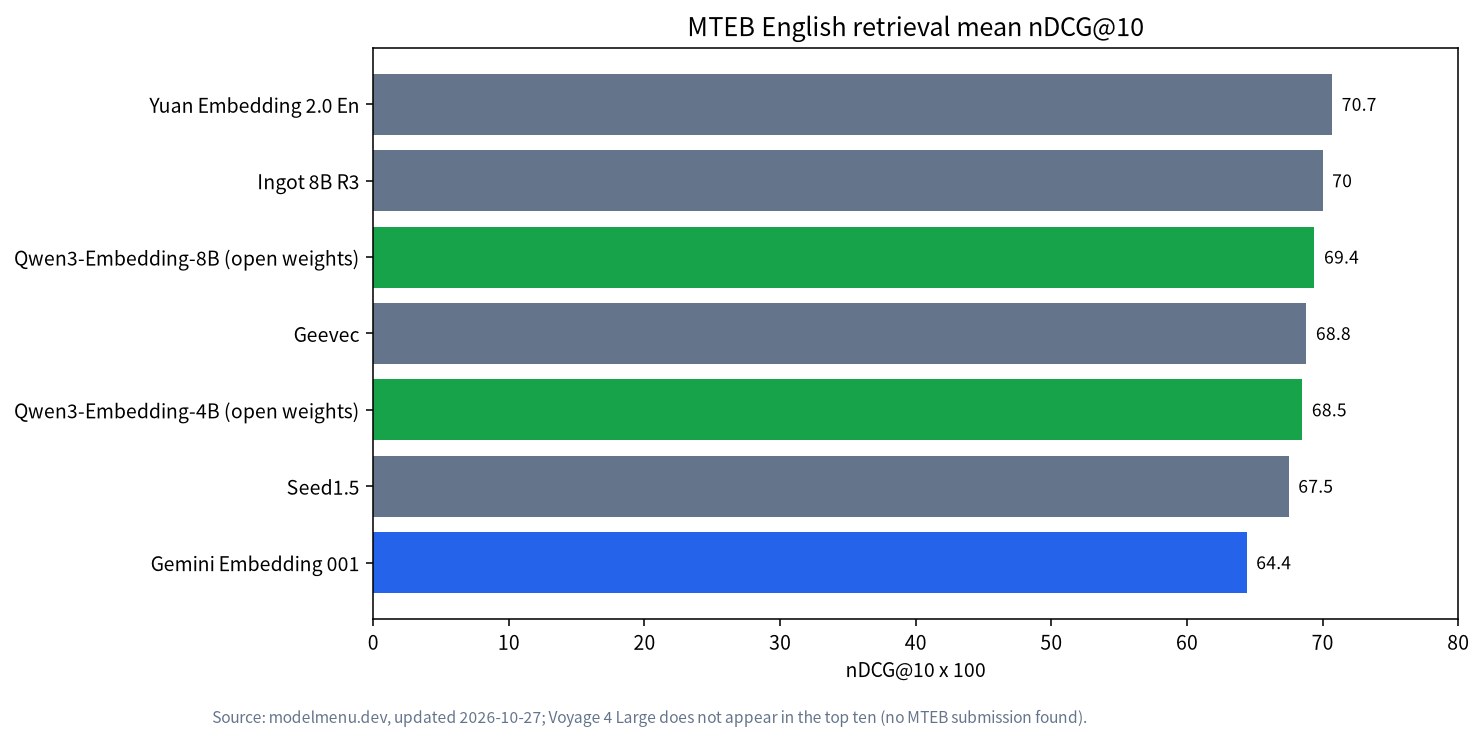
The open-weights Qwen3-Embedding-8B is third and the 4B is fifth, only about 1.3 and 2.2 points behind the leader. For anyone building retrieval locally this is the important fact: on the public board, open weights are already in the top tier. As for Voyage 4 Large, we did not find its score on this board.
The Voyage 4 Design: A Shared Embedding Space
One distinctive design choice of the voyage-4 family is that voyage-4-large, voyage-4, voyage-4-lite and voyage-4-nano share one embedding space. That means you can embed documents with a larger model (a one-off offline job) and embed queries with a smaller, cheaper or even local nano model, and the vectors remain directly comparable without rebuilding the index when you change models. The company also says voyage-4-large uses an MoE architecture that serves at about 40% lower cost than a comparable dense model (vendor figure). Output dimensions are available at 2048, 1024, 512 and 256 (Matryoshka style), and data types include float, int8, uint8 and binary. The documentation gives a context length of 32,000 tokens and a default dimension of 1024.
Prices and Costs
Voyage’s official pricing page (we read this page):
| Model | Per million tokens (USD) | Free allowance |
|---|---|---|
| voyage-4-large | 0.12 | First 200 million tokens |
| voyage-4 | 0.06 | First 200 million tokens |
| voyage-4-lite | 0.02 | First 200 million tokens |
| Older voyage-3-large | 0.18 | None |
| Batch API | 33% discount on the standard price | 12-hour completion window; free tokens do not apply to batch |
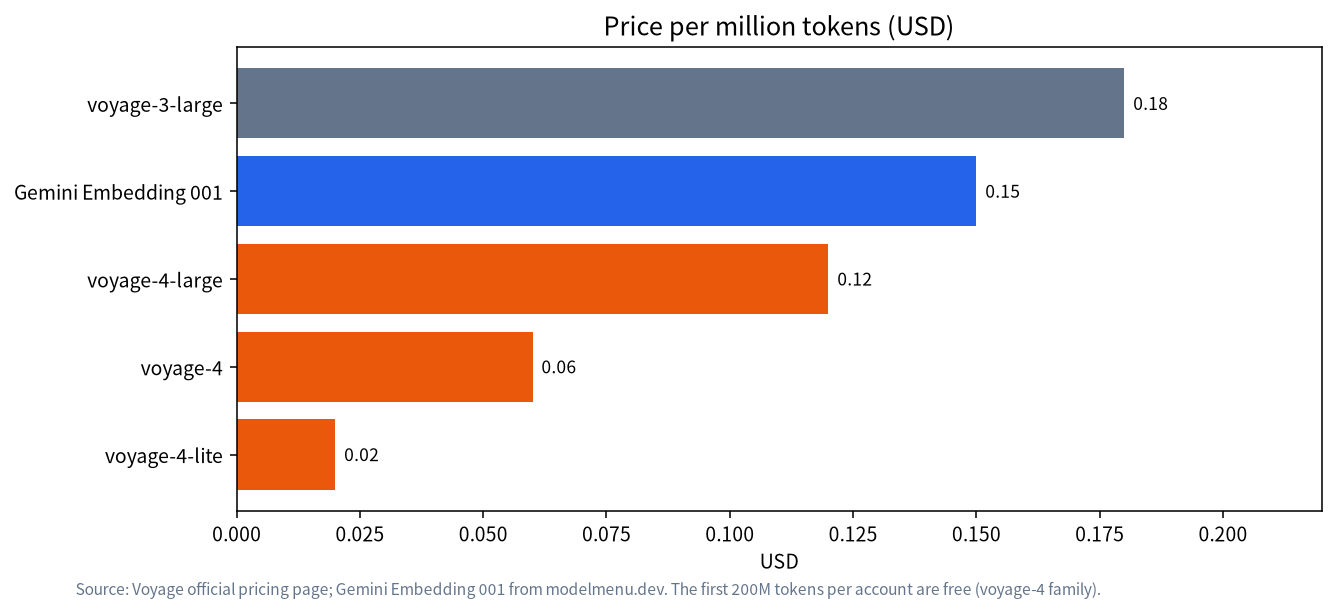
Two worked examples (our arithmetic, excluding query volume):
- A small knowledge base, 50 million tokens of corpus: within the first 200 million free tokens, so the embedding cost is zero.
- A 1 billion token corpus: after the first 200 million free tokens, 800 million tokens remain. At voyage-4-large that is about $96, at voyage-4 about $48 and at voyage-4-lite about $16. Through the Batch API (which does not draw down the free allowance), 1 billion tokens at voyage-4-large cost about $80.40.
The conclusion: the one-off embedding cost is not high in itself; the real costs come from ongoing query volume, re-embedding (when you change models or documents change) and vector storage.
Vector Storage: Dimensions and Data Type Set the Bill
Our arithmetic: bytes per vector equal dimensions times bytes per dimension. For one million documents:
| Configuration | Bytes per vector | 1 million vectors |
|---|---|---|
| 2048 dims, float32 | 8,192 | about 8.19GB |
| 1024 dims, float32 | 4,096 | about 4.10GB |
| 1024 dims, int8 | 1,024 | about 1.02GB |
| 256 dims, int8 | 256 | about 0.26GB |
| 1024 dims, binary | 128 | about 0.13GB |
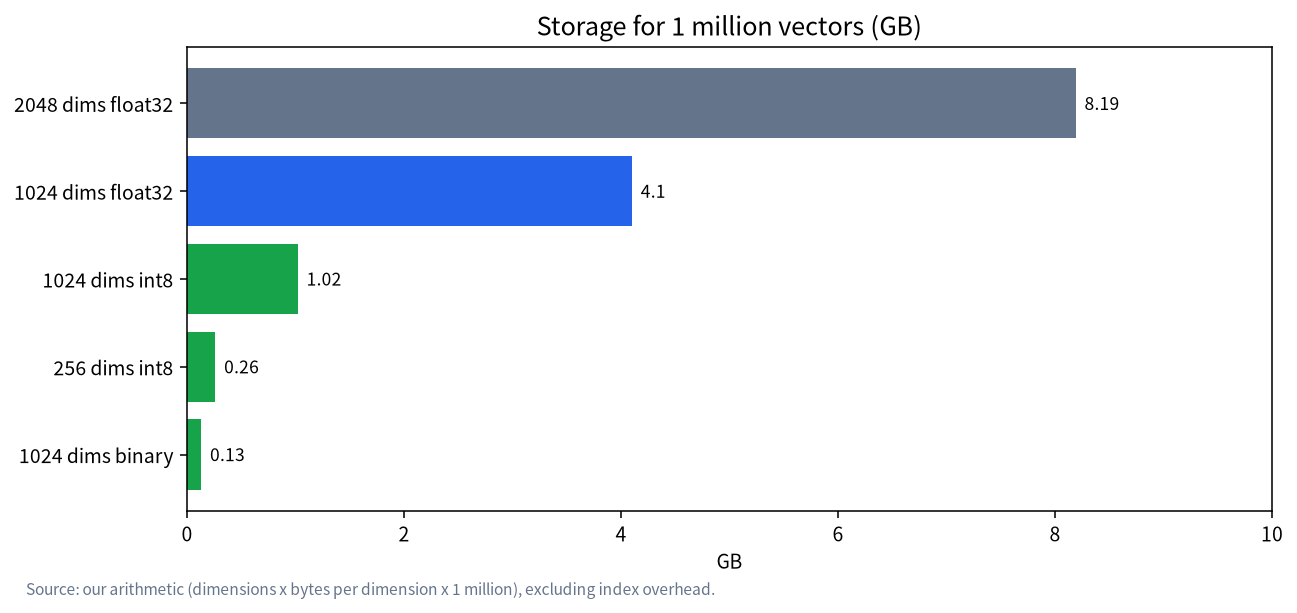
Going from 2048-dimension float to 1024-dimension int8 cuts storage to one eighth; to 1024-dimension binary, to one sixty-fourth. These compressions cost retrieval quality; we did not verify how much in this article, and you must measure it on your own data.
What You Can Run Locally: voyage-4-nano and Qwen3-Embedding
| Model | Size | Features | License and notes |
|---|---|---|---|
| voyage-4-nano | About 340 million parameters (180 million non-embedding plus 160 million embedding) | 32K context; dimensions 2048, 1024, 512, 256; shares the embedding space with voyage-4-large; a GGUF version is available for Ollama | Apache-2.0 |
| Qwen3-Embedding-0.6B / 4B / 8B | 0.6B, 4B, 8B | 32K context, dimensions up to 4096 (customizable from 32 to 4096); 100+ languages and instruction support; official MTEB multilingual scores 64.33, 69.45, 70.58 (June 2025), C-MTEB Chinese 66.33, 72.27, 73.84 | Check the model card for the license; not verified here |
Qwen3-Embedding-8B’s weights are about 16GB by parameter count (BF16, our arithmetic), the 4B about 8GB and the 0.6B about 1.2GB, excluding activations and batching overhead at inference time. For Chinese-speaking readers the C-MTEB figures are especially useful: 73.84 for the 8B and 72.27 for the 4B. To build a local retrieval system see building a local knowledge base RAG and Dify and RAGFlow local deployment; for hardware see the GPU VRAM guide.
How to Choose: Paid Flagship or Local Model
| Your situation | Lean toward | Reason |
|---|---|---|
| Data cannot leave your machine | Qwen3-Embedding or voyage-4-nano | Open weights, run locally |
| Mostly Chinese, and local | Qwen3-Embedding-4B or 8B | Strong C-MTEB figures, 100+ languages |
| Need to ship fast with a small corpus | voyage-4-large (API) | First 200 million tokens free, simple integration |
| Want lower query cost but flagship quality | Flagship for documents, nano for queries | Shared embedding space, no index rebuild |
| Storage-sensitive | Fewer dimensions plus int8 or binary | Down to under one eighth the size, but test quality |
Query Cost: The Underrated Line Item
Many people count only the one-off document embedding fee and forget that queries generate cost every day. A worked example (our arithmetic, assuming about 30 tokens per query and ignoring the free allowance): 100,000 queries a day is 3 million tokens a day, or about 90 million tokens a month. At voyage-4-large that is about $10.80 a month, and at voyage-4-lite about $1.80 a month. Both are small, but if your query volume is a hundred times that the difference becomes noticeable; and if queries are embedded locally with a nano model, the marginal cost is close to zero, leaving only electricity. That is exactly the value of a shared embedding space: embed documents once with the large model, and embed queries locally with the small one.
How to Read a Vendor’s “Ahead by X%”
The Voyage blog says “3.87% higher than Gemini Embedding 001 and 14.05% higher than OpenAI v3 Large”. There are three points to keep in mind. First, these are relative gaps, not absolute scores; we did not see a full table of absolute scores in the blog that we could reproduce here, so do not convert them into “NDCG points gained”. Second, the comparison set is chosen by the vendor, and the open-weights Qwen3-Embedding from the public board does not appear in the blog; that does not mean they are better, only that the comparison cannot answer “how does it stack up against open-weights models”. Third, an average hides the distribution: a model can be worse on one dataset and better on another and still lead on average, and your data may happen to fall in the weaker class. For how to read boards see how to read model benchmarks.
A 32K Context Is Not an Invitation to Fill It
The documentation gives a context of 32,000 tokens, and Qwen3-Embedding is also 32K. But for retrieval, stuffing a whole long document into one vector is usually a bad idea: one vector has to represent everything in a long text, details get diluted, and the retrieved passage is so long that it fills the context you later send to the LLM. The more common practice is to split into chunks of a few hundred tokens, keep metadata such as headings, and leave some overlap between chunks. Long context is valuable when the passages themselves are long, such as legal clauses or paper sections, so you are not forced to cut them hard. For chunking and evaluation details see building a local knowledge base RAG.
Test It Yourself: An Evaluation Method
We have not evaluated these models; the procedure below lets you judge on your own data.
- Build 200 queries: from real user questions, each labeled with one to three relevant documents.
- Prepare distractors: at least 10,000 documents, including hard negatives similar to the relevant ones.
- Hold the pipeline fixed: same chunking and the same similarity (cosine), swapping only the embedding model.
- Metrics: compute Recall@10, nDCG@10 and MRR, with Chinese and English reported separately.
- Compression experiments: for each model, test 1024, 512 and 256 dimensions and int8 and binary, recording the quality drop.
- Cost and speed: record embedding time and cost per million tokens; for local runs record VRAM and electricity.
- Mixed experiment: embed documents with the flagship and queries with nano, and check whether the shared space works on your data.
Common Mistakes
- Treating a vendor measurement as a public board. Voyage 4 Large’s lead comes from the vendor’s RTEB comparison.
- Ignoring board dates. The MTEB scores on the Qwen3-Embedding model card are from June 2025.
- Counting only embedding fees, not storage and re-embedding. Long-run cost often sits in those two.
- Compressing vectors without testing quality. The loss from int8 or binary depends on your data.
- Mixing embedding spaces. Only the voyage-4 family claims a shared space; do not mix its vectors with other vendors’ vectors.
Related Reading
- Building a local knowledge base RAG
- Dify and RAGFlow local deployment
- AnythingLLM tutorial
- GPU VRAM guide
- How to read model benchmarks
FAQ: Voyage 4 Large
Is Voyage 4 Large the best embedding model?
In Voyage’s own published RTEB comparison it leads the Gemini Embedding 001, Cohere Embed v4 and OpenAI v3 Large it compares against. But we did not see it in the top ten of the public MTEB English retrieval board.
How much does Voyage 4 Large cost?
The official pricing page states $0.12 per million tokens, with the first 200 million tokens per account free; the Batch API has a 33% discount.
Is there a version I can run locally?
Yes, voyage-4-nano: Apache-2.0, about 340 million parameters, shares the flagship’s embedding space and has a GGUF version for Ollama.
Can Qwen3-Embedding replace it?
On the public MTEB English retrieval board Qwen3-Embedding-8B scores 69.4, third. Whether it can replace Voyage depends on your data; test it using the method in this article.
How should I pick the vector dimension?
Higher dimensions usually give better quality but more storage. 1024-dimension int8 is one eighth the size of 2048-dimension float32; measure the loss yourself.
Which model for Chinese retrieval?
Qwen3-Embedding’s C-MTEB Chinese scores are 73.84 for the 8B and 72.27 for the 4B. We did not find independent Chinese data for Voyage 4 Large.
Talk With Us
Building local retrieval or a RAG system? Join the community or email admin@microaione.com.
References: Voyage AI blog: voyage-4, Voyage official pricing, Voyage embeddings documentation, modelmenu.dev MTEB board, Hugging Face: voyage-4-nano, Hugging Face: Qwen3-Embedding-8B.